


This is your annual budget
But budgets get exhausted.
Spend is climbing ~4× year over year.
Every query, every agent step, every retry burns tokens — and someone pays for all of them.
Off-the-shelf agent

Glean context layer
Bad AI architecture ate your token budget
Glean Assistant saved 81% on token costs versus Claude Cowork.
Token costs is an
AI architecture problem,
not just a model problem.
AI architecture problem,
not just a model problem.
Everyone measures token costs.
Almost no one measures the value delivered per token.
Token efficiency and lower cost per token deliver the cost savings.
70%
Token efficiency
x
31%
Lower cost per million tokens
=
81%
Token savings per task
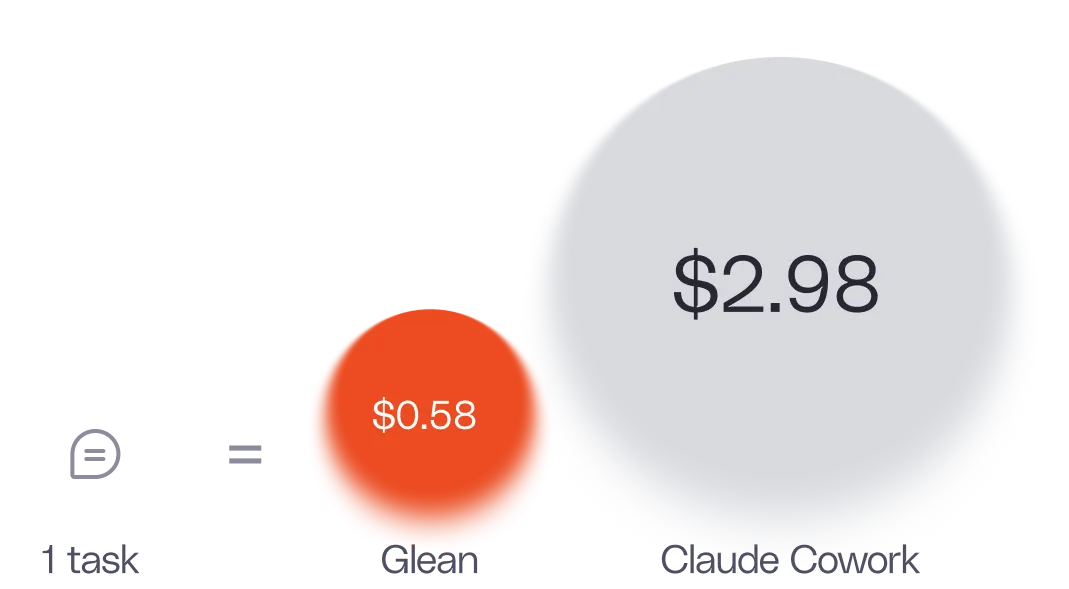
At $2.98 per task, running Claude Cowork across thousands of employees can become an expensive line item in your budget. Glean is more token efficient and routes across model providers instead of paying frontier prices by default.
Token yield maximizes useful outputs per token spent.
Overall preference
Completeness
Correctness
Interaction quality
74% win rate.
On the queries where graders picked a winner, Glean won 74% of the time — leading on every evaluation component, with correctness its biggest advantage.
Every department. Glean won.
Sales
Marketing
HR/People
Engineering
Finance
Support/Success
Product
Glean's output is preferred by every department, including sales, marketing, HR, engineering, and finance.
Want to calculate what the gap costs at your scale?
Employees using AI

Tasks per employee per day

$94.4M
you could save annually.
Watch your tokens burn. Then watch Glean save them.
Summarize a 40-page board
Start
Draft a follow-up from account history
Glean
Tokens consumed
40
Cost/run
$20.0
Claude Cowork
Tokens consumed
40
Cost/run
$20.0
Continue scrolling