
How do you move an AI agent from a successful pilot to consistent measurable ROI across your organization?
Moving an AI agent from a successful pilot to consistent, measurable ROI takes treating scale as an operating-model change, not a larger deployment. You standardize the context, controls, and rollout pattern that made the pilot work, then extend it to one adjacent workflow at a time.
A pilot proves an agent can work in one place. Scaling proves it works repeatedly across teams that never gave it special attention, with shared context, governance, and clear ownership.
The reason to scale is business outcomes, not novelty: faster resolution times, lower cost to serve, and capacity returned to your teams. Those gains hold only when the agent runs with the same context and controls everywhere, not just in the pilot.
How to move an AI agent from a successful pilot to consistent, measurable ROI across your organization
Start with the workflow, not the model. The fastest path to AI agent implementation is a specific bottleneck where people lose time finding information, stitching context across tools, or repeating the same steps, such as ticket triage, account research before a renewal, or on-call runbook lookups. Choosing that workflow first defines what the agent must retrieve, what it should act on, and how you will measure whether it helped.
Treat scaling AI initiatives as an operating-model problem, not a technical one. In a July 2026 BCG survey of 152 large-enterprise CEOs, nearly two-thirds said their company runs AI pilots, but only 26% have embedded AI as part of a broader business transformation, a sign of how many struggle to scale. A pilot often succeeds because a small team gave it extra care, curating data and reviewing outputs by hand. Organization-wide ROI depends instead on shared context, common controls, and a rollout pattern other teams can reuse.
The distance between a promising pilot and repeatable production value is where most programs stall. Gartner forecasts that over 40% of agentic AI projects will be cancelled by end of 2027, citing unclear business value, escalating costs, and inadequate risk controls more than model quality. Deloitte reported in 2026 that only 25% of enterprises had moved 40% or more of their pilots into production.
Anchor the business case in measurable outcomes before you build. For the first workflow, define:
- what improves, in the team's own terms
- how it is measured against a baseline
- who owns the workflow and its results
- what evidence leadership will accept as proof
Keep enterprise AI strategies practical by moving from one high-confidence use case to the next adjacent one. Ground each agent in permission-aware retrieval and cited, grounded answers so it acts on what a user is allowed to see, not a separate copy of the data. The rest of this article follows that path in order: choose the use case, set a baseline, ground the agent in enterprise context, govern its actions, standardize the rollout, expand to adjacent workflows, and measure ROI throughout.
1. Pick one workflow with a clear cost of delay
Pick a single workflow that costs the business real time or money every day, and where you can see the delay plainly. The strongest first candidates are high-volume, repetitive, and important: knowledge retrieval, drafting, triage, routing, summarization, or coordinated actions across systems. Prioritize work where employees lose time searching scattered apps, recreating existing knowledge, or waiting on manual handoffs, because that is where AI workflow optimization compounds.
Check for readiness signals before you commit:
- clear owners for the process and its outcomes
- available source content the agent can retrieve
- stable, repeatable process steps
- measurable before and after metrics
- low ambiguity about what a good result looks like
Good early AI use cases share those traits: support case resolution, sales account research, onboarding questions, policy guidance, engineering knowledge lookup, and internal service desk requests. The best early AI agents sit inside workflows where context already exists but is hard to access in the moment. Avoid broad goals like "improve productivity across the company." They are too diffuse to prove and too vague to govern.
Screen each candidate with five questions: is the problem frequent, is it costly, is it measurable, is it grounded in company knowledge, and is it safe to automate with clear escalation paths? If a workflow is already broken, fix it first. An agent accelerates the process it inherits, including its errors.
2. Set a baseline before you expand
Do not move from pilot to rollout until you know the human baseline. Without it, measuring AI ROI becomes storytelling instead of evidence. Capture the before state in concrete terms: time to complete, tools touched, time to answer, rework rate, escalation rate, SLA performance, and cost per task or resolution.
Add quality measures, not only speed: accuracy, completeness, policy adherence, and user trust. Faster wrong answers do not create value. Separate leading metrics from business metrics so you know what each one tells you:
- Leading metrics: adoption, query success, fallback rate, citation use, and approval rate.
- Business metrics: time saved, case deflection, cycle-time reduction, faster onboarding, and capacity unlocked.
Define success thresholds in advance, and measure results by role and department. Include total operating cost, covering implementation, tuning, governance overhead, and usage, not just launch spend.
Strong AI performance metrics answer three leadership questions: is it used, does it work, and does it improve the business outcome enough to justify expansion? Forbes Research found in 2025 that 39% of C-suite executives cite measuring ROI and business impact as a primary challenge, which is the gap a baseline closes.
3. Ground the agent in enterprise knowledge, context, and permissions
AI pilot success often rests on curated data and a forgiving audience. Scaling fails when the agent reaches new teams without the same context, and reliability on multi-step tasks drops sharply outside the pilot's controlled setup, so ground it in real enterprise knowledge before you widen access.
Connect to real sources: documents, tickets, chat, wikis, file systems, CRM, issue trackers, and HR systems. The goal is one working knowledge layer, not another silo, so use broad connectors and APIs that fit the environment you already run.
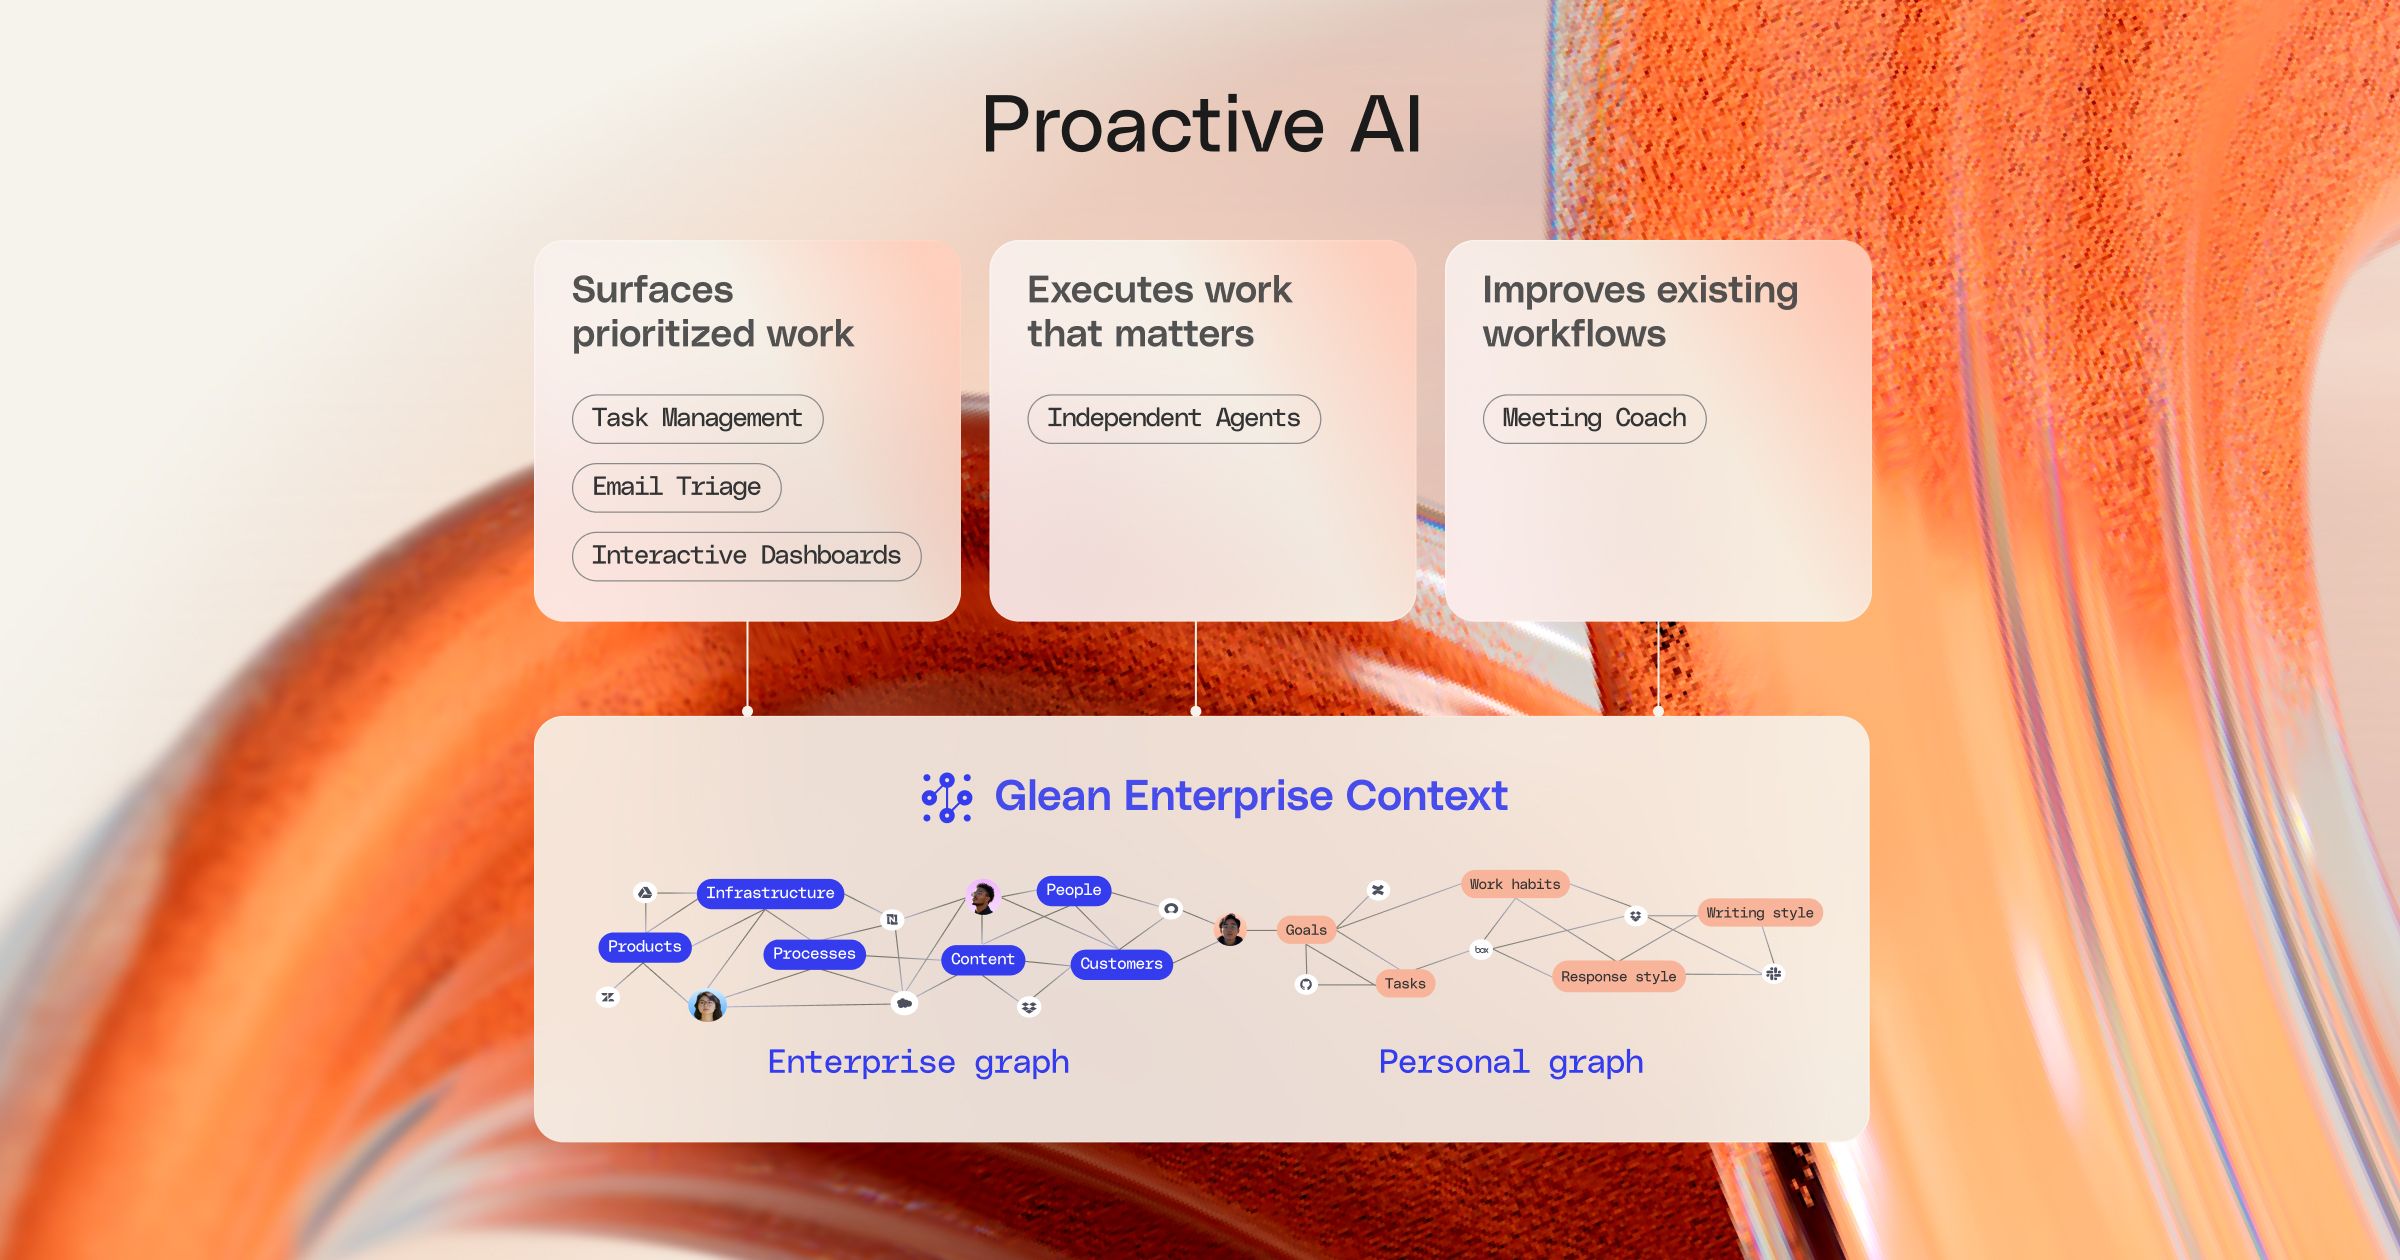
Ground answers in retrieved company content and show citations so users can verify what they read. Preserve existing permissions at retrieval time, before generation, so the agent uses only what the employee is allowed to see. Glean enforces this upstream of the LLM through the Enterprise Graph, so a new team inherits the same access rules the pilot ran on.
Add organizational context as well: who people are, how teams are structured, how work moves, and which systems of record hold the truth. Make actions as grounded as answers, so an agent that updates a record relies on the same verified context it uses to reply.
If the pilot depended on manual copy-paste, hand-built prompts, or isolated data exports, it is not ready to scale. Those shortcuts do not survive contact with teams that never tended the setup.
4. Put governance and human review into the operating model
AI governance belongs in the rollout plan from the start, not bolted on after the first incident, especially since security and risk concerns are the leading obstacle organizations cite to scaling agentic AI. Classify each workflow by risk: low-risk work like summarization needs lightweight review, while higher-risk work like approvals, policy interpretation, or system updates needs stronger controls. Define clear action boundaries for what the agent can answer, what it can draft, and what it can trigger, and set the point where a human must approve before anything changes in a live system.
Build the controls into the operating model:
- role-based access and audit logs
- testing environments, version control, and rollback paths
- an escalation model for low-confidence answers, conflicting sources, missing permissions, stale content, and out-of-scope tasks
Make ownership explicit across four roles: business owner, technical owner, content owner, and governance owner. Manage rollout through an enterprise agent development lifecycle that covers design, evaluation, approval, deployment, measurement, and iteration.
Human-in-the-loop review is not weak automation. It builds trust and collects the evidence you need to widen autonomy safely. The need is well documented: Deloitte found in 2026 that only 21% of organizations have a mature governance model for agentic AI, and roughly 80% lack clear human-approval boundaries, monitoring, and audit trails.
5. Standardize the deployment pattern before adding more teams
Rebuilding an agent from scratch for each department is how scaling AI initiatives stalls. Once one workflow works, create a repeatable pattern for deployment, evaluation, permissions, and support that the next team can reuse. Standardize the core layers so reuse becomes the default rather than a decision each group relitigates:
- knowledge connections to source systems
- prompt and policy controls
- the action framework
- analytics and reporting
- the access model
- the review process
Build one common way to test quality before launch, run against real workflow examples: relevance, groundedness, permission behavior, task completion, and failure handling. Put the agent where people already work, inside existing collaboration tools, browsers, and business systems, and create role-specific entry points so each team meets it in context.
Document a rollout playbook that covers how a use case is requested, approved, configured, tested, launched, measured, and supported. Treat enablement as part of the product, not a step you add later. Standardization turns one pilot success into reliable AI agent best practices. Without it, every deployment becomes another custom project.
6. Expand use cases by adjacency, not by enthusiasm
After the first workflow proves value, expand to the next use case that shares the same knowledge foundation, governance model, and audience. Adjacent AI use cases are the safe next step because their context overlaps with what already works. A support agent that answers questions can grow into triaging tickets, summarizing cases, and routing requests. A sales research agent can extend into meeting prep, follow-up drafting, and account intelligence.
Score each candidate with a prioritization rubric covering business impact, data readiness, governance fit, implementation complexity, and adoption likelihood. Resist rolling out to every department at once. Enterprise scale is a controlled sequence that compounds value, so pick a few flagship departments such as support, sales, engineering, HR, and IT. Keep enterprise AI strategies disciplined by using a decision framework like the one in a CIO's guide to AI agents: start with business value, confirm context and controls, then scale where governance and adoption keep up.
Adjacency reuses validated sources, permissions, review paths, and training the earlier workflow already established. Each new agent inherits proven groundwork instead of recreating it, which is what produces compounding ROI as the portfolio grows.
7. Measure business outcomes continuously and tune the system
Scaling AI agents from pilot to measurable ROI does not end at deployment. Consistent returns come from ongoing measurement, content maintenance, evaluation, and workflow refinement. Review at three cadences so signals stay tied to decisions:
- Weekly operational signals: adoption, latency, fallback rate, citation use, handoff rate, and task completion.
- Monthly team outcomes: resolution time, cycle time, and capacity gains.
- Quarterly portfolio ROI and expansion decisions.
Tie AI performance metrics to the workflow the agent runs. For a knowledge agent, track time to answer, answer quality, and source freshness. For an action agent, track task completion, approval rate, exception rate, and downstream rework. Monitor trust directly as well. When users bypass the agent or verify every answer by hand, the quality and context model needs work.
Tune with evidence: update content, improve retrieval, refine prompts and tools, narrow scopes, and retire use cases that do not improve outcomes. Compare the scaled deployment against the original pilot, then report results in leadership language: cost avoided, hours returned, SLA improvement, faster ramp, lower support load, better throughput, and added capacity without proportional hiring. The stakes are clear in the data. McKinsey found in 2026 that only 37% of organizations report any EBIT impact from AI, and a durable measurement model is what separates high performers from the rest.
Frequently asked questions
What are the key steps to scale an AI agent from pilot to production?
Pick one workflow with a clear cost of delay, set a human baseline, and ground the agent in permission-aware enterprise knowledge with cited answers. Build governance and human review into the operating model, standardize a reusable rollout pattern, then expand to adjacent workflows while measuring business outcomes throughout.
How do you measure the ROI of an AI agent effectively?
Start from a baseline captured before launch, then compare production results against it. Track business outcomes like time saved, case deflection, and cycle-time reduction, not usage alone. Include total operating cost, covering tuning and governance, and report in leadership terms: hours returned, cost avoided, and capacity gained.
What metrics should be tracked to ensure consistent performance of AI agents?
Watch operational signals weekly, including adoption, latency, fallback rate, citation use, handoff rate, and task completion. Review team outcomes monthly, such as resolution time and capacity gains. Match metrics to the agent type, and check whether people trust answers or feel they must verify each one manually.
What common challenges show up when moving from pilot to full deployment?
Weak baselines, pilot data too narrow to generalize, missing permission logic, unclear ownership, and no standard rollout pattern all stall progress. Teams also over-automate too early and deploy disconnected agents without a shared context layer, so value that looked strong in a sandbox erodes once real teams depend on it.
How can organizations identify the right use cases for AI agents to maximize ROI?
Score candidates on business impact, data readiness, governance fit, implementation complexity, and adoption likelihood. Favor frequent, costly, measurable workflows grounded in company knowledge with safe escalation paths. Start adjacent to a workflow that already works, so context, permissions, and review paths carry over and returns compound instead of resetting.
Getting an agent from a promising pilot to organization-wide ROI is a repeatable discipline, not a one-time win. When you set a baseline, ground each agent in permission-aware answers from your own knowledge, add governance, and expand by adjacency, your early wins become results you can measure and defend. Request a demo to see how we can put your enterprise knowledge to work with AI.