
Which everyday work questions should you use to shortlist enterprise AI search platforms for software engineering teams?
Use everyday engineering questions — about incidents, onboarding, cross-tool context, security, and productivity — to shortlist enterprise AI search platforms by testing each one with the real questions your engineers ask every day, then score every answer on accuracy, citations, speed, and permission safety.
Everyday work questions expose what vendor demos and feature checklists hide. Asking "Who owns the payments service, and what changed last sprint?" shows whether a platform can combine source control, tickets, and chat in one answer.
Engineering knowledge lives in repositories, wikis, CI/CD logs, design docs, and pull request comments, so it's a demanding test for any enterprise AI search platform. The questions below cover incidents, onboarding, cross-tool synthesis, security, and productivity measurement.
Why do software engineering teams need a different evaluation approach than other departments?
Engineering knowledge is technical, version-sensitive, permission-layered, and spread across more specialized systems than most functions use. A generic enterprise AI search evaluation checks whether a platform retrieves documents. An engineering evaluation checks whether it understands code context, system relationships, and which answer is current today.
Engineers switch between software engineering tools all day, and Atlassian found developers spend only 16% of their time coding: source control, issue trackers, CI/CD pipelines, observability dashboards, wikis, and chat. Each tool has its own search bar, and none of them talk to each other. When search fails, engineers interrupt a teammate or give up.
Stack Overflow's 2024 Developer Survey found 61% of developers spend more than 30 minutes a day searching for answers or solutions. Atlassian's 2025 State of DevEx report ranks finding information (services, docs, and APIs) among developers' top time-wasters. That search time comes out of writing, reviewing, and debugging code.
Three traits of AI in software development make engineering questions harder than general ones:
- Answers change with every release, so a six-month-old design doc can be confidently wrong.
- Context spans code and conversation, like a decision made in a pull request thread and never written down.
- Access is layered by repository and project, so a contractor should see only the repos they're authorized for.
Which questions test whether a platform can resolve incident and debugging scenarios?
Incident questions are the toughest test because they're urgent and need context from several systems at once. Ask about recent changes, repeat errors, and on-call history using your own connected data. Strong platforms return one cited, synthesized answer across tools. Weak ones return stale wiki pages or make the engineer pick which tool to search.
Run these three questions during a live evaluation:
- "What changed in the checkout service in the last 48 hours?" A good answer merges commits, deploys, config changes, and tickets into one timeline.
- "Have we seen this error before, and how was it fixed?" Matching should work on stack traces and postmortems, even with different wording.
- "Who was on call last weekend, and what did they escalate?" The answer requires knowing people and schedules, beyond documents.
The repeat-error question is where hybrid retrieval earns its keep. Lexical search matches exact strings like NullPointerException or an error code, while semantic search matches meaning. A postmortem rarely quotes the stack trace word for word, so incident AI search use cases need both.
Grounded answers come from retrieval-augmented generation (RAG), which feeds retrieved documents to a language model before it responds. During the pilot, click every citation. Each one should open the exact commit, deploy log, or ticket, so a responder can verify it before rolling anything back.
Which questions test onboarding and codebase navigation?
Onboarding questions test whether a platform connects code to the reasons behind it and the people who know it. New engineers spend weeks rebuilding mental models that already exist in docs, review comments, and old decisions. Ask where logic lives, which conventions apply, and who to ask, then compare answers to what a senior engineer would say.
Four questions cover most of a new hire's first month:
- "Where is the API rate-limiting logic, and why was it designed that way?" Look for code locations paired with architecture decision records.
- "What are this repo's error-handling conventions?" Good answers draw on style guides, README files, and recurring code review comments.
- "Who should I ask about the customer analytics data pipeline?" Expertise should come from contribution patterns and code ownership, beyond a static org chart.
- "What does this service depend on, and which dependencies had recent issues?" The answer spans service catalogs, dependency graphs, and incident logs.
Expertise questions separate platforms that build a knowledge graph from ones that only index files. A knowledge graph links people, content, and activity. It can rank the engineer who reviewed most pipeline changes last quarter above the doc's author, who moved teams a year ago.
Have a tech lead grade the onboarding answers. A confident answer that points to a deprecated module sends a new hire down the wrong path for days, and in Stack Overflow's 2025 survey 46% of developers said they distrust the accuracy of AI tool output.
Which questions test cross-tool search and context synthesis?
Cross-tool questions check whether a platform can combine facts from different systems into one accurate, cited answer. Project status, past decisions, and compliance work rarely live in a single tool. Test with questions whose answers you already know span four or five sources, then note which sources the platform found and which it missed.
Use questions like these:
- "What's the status of the migration to the new auth provider?" The answer spans an epic, pull requests, a design doc, and Slack.
- "What did the team decide about adopting GraphQL?" The platform must tell an RFC proposal apart from the final call in meeting notes.
- "Show me everything on GDPR changes in our user data services." Results should include legal docs, engineering tickets, and code changes.
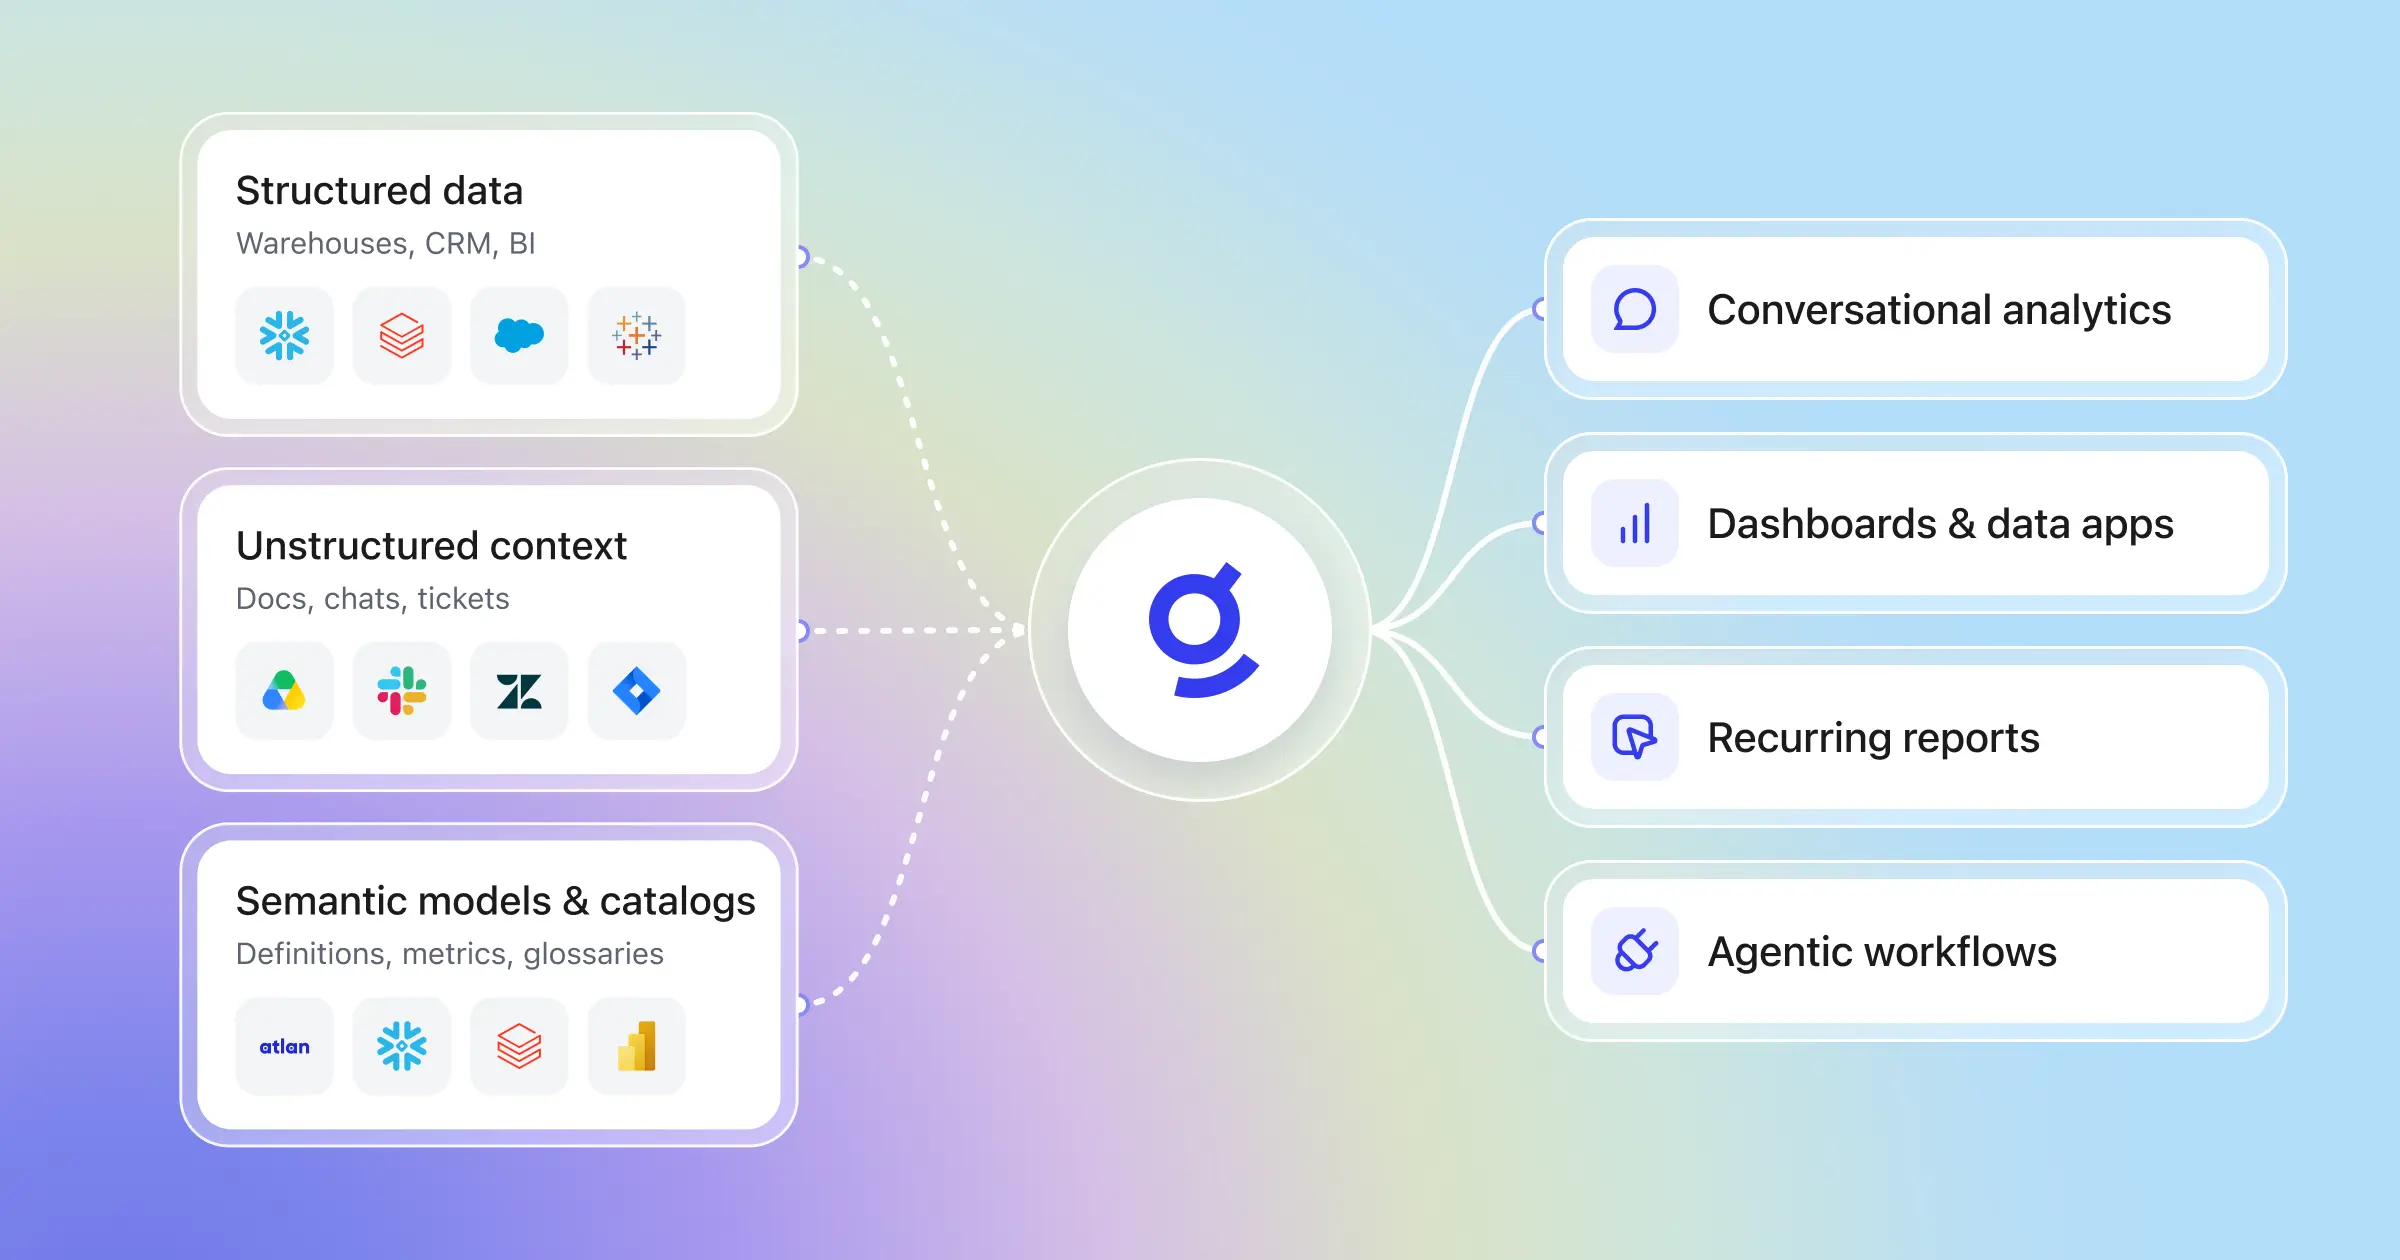
Connector coverage sets the ceiling for synthesis in enterprise AI search for software engineering teams. List the tools your team relies on: source control, CI/CD, observability, wikis, project management, and chat. Ask which have native connectors and how often each one syncs content and permissions.
For scale, our connector directory lists 275+ out-of-the-box connectors. The Glean features comparison explains why general-purpose assistants handle broad questions well, while search grounded in your connected data answers questions specific to your team.
Run the migration status question twice, a week apart. If the answer stays the same after new pull requests merge, connector sync is lagging behind your team's real work.
Which questions test security, permissions, and governance?
Security claims need verification with real test cases during the pilot. Create test accounts with different access levels, then ask questions that should return restricted content for one user and nothing for another. Check how fast revoked access takes effect, what gets logged, and whether your code or documents reach third-party model providers.
Put these questions to every vendor:
- "Can a Team A frontend engineer see results from Team B's private security repo?" Results should mirror the access controls in your source systems.
- "After revoking access to a Confluence space, how fast do results change?" We recommend setting your bar at minutes, since slower sync creates leakage risk.
- "What audit trail shows who searched for what and which results they saw?" Regulated teams need this record for compliance reviews.
- "Does our proprietary code reach third-party LLM providers, and under what retention terms?" Ask for contractual zero-day retention guarantees.
Ask where permissions are enforced. Permission-aware search applies each source system's access rules at retrieval, upstream of the language model, so the model never receives content the user can't open. Filtering after generation is weaker, because restricted content has already shaped the answer.
Our post on agentic reasoning explains how we enforce permissions before content reaches the LLM. It also covers our zero-day retention agreements with model providers.
How do you measure whether a platform actually improves engineering productivity?
Google's 2025 DORA report puts AI adoption among software development professionals at 90%, so the question is impact, not use. Measure productivity with metrics you can observe during a pilot. Track time-to-answer, context switches, onboarding ramp, and internal question deflection against a baseline taken before rollout. Ask vendors for outcomes from engineering teams of similar size and tooling, since company-wide averages hide what matters to developers.
| Metric | How to measure it | What improvement looks like || --- | --- | --- || Time-to-answer | Time a common question like "Where is X implemented?" with and without the platform | Seconds instead of minutes of multi-tab searching || Context switches | Count daily exits from the IDE, terminal, or chat to look something up | Fewer exits once browser extension and chat integrations are live || Onboarding ramp | Days until a new hire's first meaningful pull request or resolved ticket | A shorter ramp than your previous hiring cohort || Internal question deflection | Share of "where is..." questions in engineering Slack channels answered before a human replies | A rising share across the pilot |
Capture baselines in the two weeks before the pilot starts. Without baselines, gains from software engineering productivity tools stay estimates, and estimates rarely survive a budget review.
To turn time saved into ROI, multiply hours saved per engineer per week by headcount and loaded hourly cost. That number makes enterprise AI benefits concrete for finance: Atlassian estimates organizational inefficiencies cost a 500-developer company roughly $7.9 million a year. Each hour not spent searching goes back to reviewing and shipping code.
How to structure your shortlist evaluation using these questions
A structured shortlist has three parts: a question bank from real work, a scored pilot with identical vendor inputs, and a test beyond retrieval. Running the same questions against the same data makes vendors comparable. Treating permission failures as disqualifying keeps unsafe platforms off the list.
Build a question bank from your team's real workflows
Collect 15 to 20 questions your engineers asked in the last month. Pull them from Slack, standup notes, onboarding docs, and incident retrospectives. Real questions make better questions for AI platform selection than anything a vendor scripts.
Tag each question by category: incident response, onboarding, code navigation, cross-team coordination, compliance, or architecture decisions. Weight categories by how often they come up and what a slow answer costs. A team that loses the most hours to debugging should weight incident questions highest.
Record the correct answer and its source next to each question before the pilot begins. Graders then score against a known answer instead of a gut feeling.
Run a structured pilot with scoring criteria
Evaluating AI search solutions side by side works only when every vendor gets the same questions and connected sources in a time-boxed pilot. Score each answer from one to five on four dimensions:
- Accuracy, checked against the answer you recorded
- Completeness, meaning the answer covers every relevant source
- Citation quality, meaning each claim links to a source you can open
- Latency, measured from question to full answer
Have two engineers grade independently and review any score that differs by more than one point. Disqualify any platform that shows a test user content they shouldn't access. One permission failure is enough.
Evaluate beyond retrieval
Strong platforms connect answers to action. Check whether you can create tickets, summarize threads, draft documentation, and trigger workflows from the same interface where the answer appears.
Ask whether the platform supports agents that plan and run multi-step tasks under enterprise governance. A practical test is turning a bug report into a ticket with linked logs, the likely owner, and similar past incidents.
Favor platforms that deliver unified search for your team today, with a clear path to AI assistants and agents as adoption grows.
Frequently asked questions about evaluating enterprise AI search for software engineering teams
What makes enterprise AI search evaluation different for software engineering teams than for other departments?
Engineering knowledge is version-sensitive, permission-layered, and spread across specialized tools like source control, CI/CD pipelines, and observability dashboards that general-purpose search tools were not built to index. A useful evaluation must test whether the platform understands code context, system relationships, and which answer is current — not just whether it retrieves documents.
How many questions should you include in a pilot evaluation question bank?
Collect 15 to 20 questions drawn from real engineering work in the last month — pulled from Slack, standup notes, onboarding docs, and incident retrospectives. Tag each by category (incident response, onboarding, compliance, etc.) and record the correct answer and its source before the pilot begins so graders score against a known answer rather than a gut feeling.
How do you verify that an enterprise AI search platform enforces permissions correctly?
Create test accounts with different access levels and ask questions that should return restricted content for one user and nothing for another. Check how quickly revoked access takes effect — minutes is the recommended bar — and confirm that permissions are enforced at retrieval, before content reaches the language model, not filtered after generation.
Which productivity metrics should you track during an enterprise AI search pilot for engineers?
Track time-to-answer, daily context switches out of the IDE or terminal, onboarding ramp (days to first meaningful pull request), and internal question deflection in engineering Slack channels. Capture baselines in the two weeks before the pilot starts; without baselines, productivity gains remain estimates that rarely survive a budget review.
What should you test beyond basic retrieval when evaluating an enterprise AI search platform?
Check whether the platform can connect answers to action — creating tickets, summarizing threads, drafting documentation, and triggering workflows from the same interface. Also test whether it supports agents that plan and run multi-step tasks under enterprise governance, such as turning a bug report into a ticket with linked logs, a likely owner, and similar past incidents.
Run your own question bank against your own connected data, and the gaps between platforms become clear quickly. We're glad to run that test with you, using your team's real questions and tools. Request a demo to see how we answer them with cited, permission-aware results.