
How should enterprises measure whether an AI gateway is worth it?
The clearest way to measure AI gateway ROI is a before-and-after test: a four-week baseline, then a 60- to 90-day pilot on real traffic. The gateway is worth it when the pilot shows lower cost or risk, better reliability or developer speed, and results direct provider integrations can't match.
In many enterprises, an AI gateway is the control point between applications and the models they call, as Microsoft's AI gateway documentation describes. A gateway typically authenticates and authorizes callers, balances load across backends, applies token quotas, and logs usage.
In our view, a gateway governs model traffic, yet it doesn't judge answer quality or supply permission-aware retrieval. The sections below cover how to measure AI gateway ROI with baseline metrics, cost math, and a go or no-go rule.
How should enterprises measure whether an AI gateway is worth it?
Enterprises should call an AI gateway worth it only when it beats direct provider integrations on hard numbers. Those numbers cover spend, risk, reliability, and developer velocity. Score them in a 60- to 90-day pilot with fixed workloads, a named executive owner, and a pre-pilot baseline.
Each function reads the same pilot differently, so the scorecard needs one question from each owner:
- Finance asks whether AI spend maps to a team, app, or customer without manual invoice work.
- Security asks which data left the company and which policies blocked a request.
- Platform asks whether failover, key rotation, and model onboarding got faster.
- Business owners ask whether the AI features people use became more stable or shipped sooner.
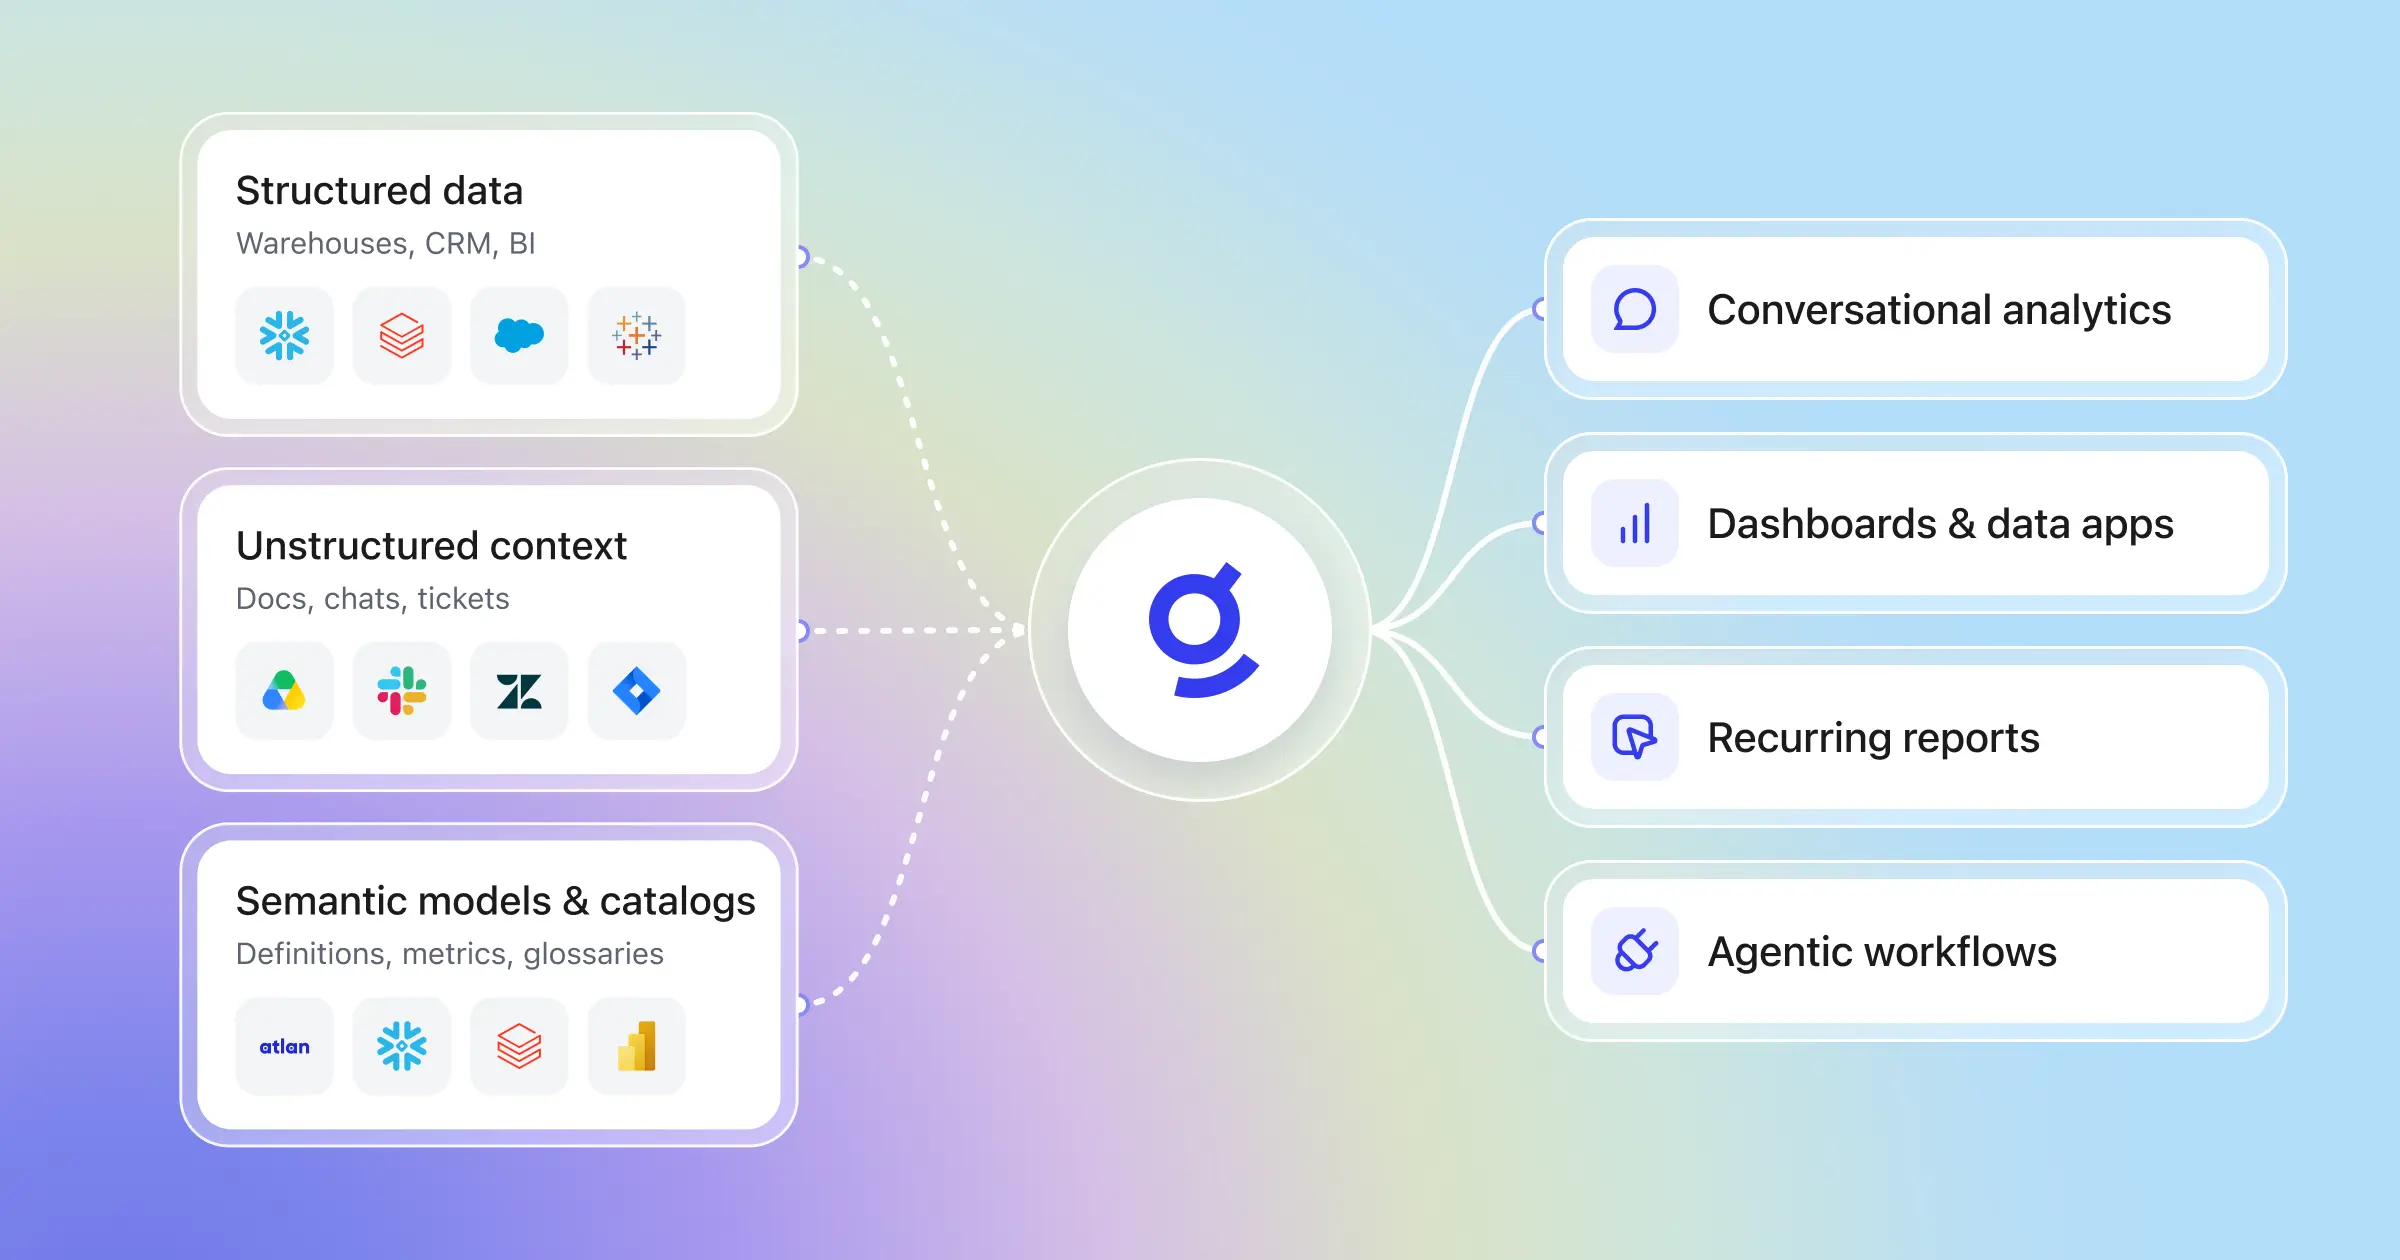
Run the pilot on real traffic, real permissions, and real workflows. Synthetic demos hide the failures that matter, such as rate-limit spikes during month-end reporting or a provider outage mid-stream. For a grounding in how the layers of an enterprise AI stack fit together, register for the platform behind enterprise AI.
1. Define the job the gateway is supposed to do
An AI gateway evaluation should start with a named problem instead of a product demo. Enterprises often buy a gateway for one of five reasons, and each reason needs its own measurable outcome. Governance is a common driver, since 44% of respondents in a Kong survey named governance and security as a top barrier to LLM adoption:
- Multi-model routing becomes the share of requests that switch providers without code changes.
- Cost control becomes the percentage of model spend attributed to a team or application.
- Policy enforcement becomes guardrail checks applied at one point instead of inside each app.
- Observability becomes the time it takes to name the app behind a usage spike.
- Centralized model access becomes fewer direct provider keys, fewer custom integrations, and faster onboarding for new AI teams.
Next, document the current architecture: providers in use, applications calling them, teams holding credentials, and controls still written in code. That inventory also shows whether you need a gateway at all. Microsoft's architecture guidance notes that multi-backend setups don't automatically require a gateway, especially with a few clients whose code you control.
In our view, one team, one model, one use case, small spend, and no compliance requirements rarely justify another control layer.
Three scoping questions keep the evaluation honest:
- Which problems come from fragmented model access today?
- Which of those problems cost enough to justify a new layer?
- Which problems need retrieval, context, or workflow orchestration instead of traffic control?
When the main complaint is untrusted answers rather than unmanaged traffic, a gateway pilot measures the wrong layer.
2. Establish a hard baseline before the pilot starts
An AI gateway pilot without a baseline produces opinions instead of numbers. Measure the current state for at least four weeks, and use one scorecard across IT, security, and business owners so success gets defined once.
- Cost metrics include monthly model spend, cost per feature, team, and user, and invoice reconciliation hours.
- Operational efficiency metrics include time to add a model, rotate keys, investigate an incident, and approve a use case.
- Performance metrics include p50 and p95 latency, timeout rate, fallback rate, and model failures visible to users.
- Governance metrics include unmanaged API keys, apps with direct model access, policy exceptions, and audit log gaps.
- Adoption metrics include active internal users, repeat use, task completion time, and whether people act on outputs.
One baseline test exposes gaps fast. Ask finance what the company spent on AI last month by team, and time how long the answer takes.
Direct provider invoices often show spend by API key or project, not by team or application, according to the FinOps Foundation. Some providers now offer native attribution, and the FinOps Foundation suggests a proxy layer when native tools fall short. Record the hours that answer requires, because the same question asked after the pilot becomes one of your clearest enterprise AI ROI numbers.
3. Measure cost control beyond the vendor invoice
The cost of an AI gateway goes well past the license fee, and finance teams are watching: 98% of FinOps practitioners now manage AI spend, according to the State of FinOps 2026 report. Total ownership includes implementation, operations, policy design, logging, storage, and support. Direct provider integrations look cheaper until spend attribution, compliance review, and incident response enter the math.
Set those ownership costs against the waste a gateway can remove:
- duplicated integrations across teams
- unmanaged key sprawl
- premium models handling routine tasks
- manual spend reporting
- outages that pull engineers into incident work
Express results in unit terms, such as cost per routed request, cost per governed application, and cost per business unit onboarded. AI-aware telemetry makes that math possible.
For example, a gateway report can show token usage per team or application. Teams can then calculate cost from each provider's pricing. In some products, the AI gateway extends the existing API gateway with controls such as token quotas.
Treat vendor savings claims as hypotheses to test on your own traffic. Semantic caching reuses responses for similar prompts, and Microsoft's AI gateway documentation says it can cut backend calls, improve response times, and help reduce costs. Your pilot should measure the actual cache hit rate and savings on repetitive workloads.
Routing routine prompts to lower-cost models can also save money, though Menlo Ventures expects net generative AI spend to keep rising even as inference costs fall. Count either saving only after it shows up in production or a controlled pilot.
4. Measure governance, security, and model management outcomes
An AI gateway pays off in governance when teams scale AI without waiting on manual reviews. A falling count of exceptions, manual reviews, and security workarounds says more than a long feature checklist. Score each control against the govern and manage functions of the NIST AI Risk Management Framework:
- Can administrators enforce approved model lists by use case or business unit?
- Can administrators set rate limits, spend limits, and logging policies in one place?
- Can audit logs capture prompts, responses, tool calls, and policy decisions in a tamper-proof, exportable form?
- Can redaction catch PII, secrets, and prompt injection, with clear logs of blocked requests?
- Can tool access follow the least-privilege guidance in the OWASP MCP Security Cheat Sheet?
AI model management needs its own metrics because most estates span several providers. More than 70% of Datadog customers sending LLM telemetry use three or more models, according to Datadog's 2026 State of AI Engineering report. Track approval time for new models, rollback speed, version visibility, and how fast you can shut off a risky endpoint everywhere.
AI governance for internal knowledge use cases has one more test. Content permissions must hold all the way to the answer. In our view, a gateway typically can't see document-level access. Glean Assistant draws on permissions-enforced enterprise search.
5. Measure reliability, performance, and developer experience in production
An AI gateway sits in every request path, so it has to make the stack more dependable without adding a fragile hop. Microsoft's architecture guidance lists performance impact and a new single point of failure among the costs a gateway adds, so test both.
Measure the overhead the gateway adds at your own peak requests per second, especially on streaming responses, where users notice delays first. Streaming behavior also depends on the policies you enable. Microsoft documents a content safety policy that buffers streamed events in a sliding window before forwarding them.
Ask vendors for their published benchmark method, then compare it with your results.
Run that test with streaming, tool use, and several models behind one policy layer, and track:
- success rate by provider and model
- fallback success rate, including which errors trigger fallback and whether it crosses providers
- mean time to detect provider issues
- mean time to recover from model outages
- change failure rate when teams add or switch models
Developer experience is the leading indicator of long-term value. Time how long it takes to connect a new app, change a routing rule, add a model, and debug a failed request. Builders who still write custom wrappers and retry logic, or who route around the gateway for speed, are a negative signal.
We frame the stack as three control layers: API gateways for service traffic, AI gateways for model access, and agent gateways for agent behavior. That split is our own model, and real products blur it. Microsoft's documentation, for example, describes its AI gateway as an extension of its API gateway.
For agent use cases, evaluate whether the gateway applies tool-call policy, keeps execution traces, and supports approvals. Glean Agents adds permissions-aware governance and real-time oversight, so the agent layer governs actions while the gateway governs calls.
6. Measure end-user impact and make a go or no-go decision
An AI gateway proves its business value when infrastructure gains show up in results people notice. Tie pilot metrics to outcomes such as faster AI feature launches, lower platform incident load, clearer spend accountability, and quicker security sign-off. Those are the signs of AI implementation success that executives already track, and the stakes keep growing as Gartner forecasts AI spending will reach $4.7 trillion by 2029.
End-user checks differ by audience. For employee-facing tools, track time to answer, context switching, repeat usage, and whether people trust answers enough to act. For customer-facing tools, track stability, response-quality review rates, escalation rates, and how fast policy updates ship when risk changes.
At the end of the pilot, apply a three-way decision rule:
- Keep the gateway if it reduced material cost, risk, or delivery time and platform teams adopted it willingly.
- Expand the gateway if it supported the multi-model plan and made governance easier to scale. Test that plan honestly, because only 11% of teams changed model providers in a year.
- Stop the gateway if it added overhead without solving the problem defined at the start.
Present the decision in an executive readout with three columns: financial return, risk reduction, and strategic flexibility. Give each column a named owner, such as the CFO, the CISO, and the platform lead, so the enterprise AI strategy decision has clear defenders.
Frequently asked questions about how to measure AI gateway ROI
What specific metrics should enterprises use to evaluate the effectiveness of an AI gateway?
Strong AI gateway evaluation metrics span money, risk, and speed. Use spend attribution accuracy, cost per request, p95 latency, success and fallback rates, audit coverage, policy exceptions, and time to onboard a model. Add one or two business signals, such as feature launch speed or active usage.
How can enterprises quantify the ROI of implementing an AI gateway?
Subtract total ownership cost from the measured change in model spend, engineering hours, incident volume, and avoided compliance work. Any benefit you can't tie to a real workflow or control stays a hypothesis until a later measurement proves it.
What are the key benefits of using an AI gateway in enterprise settings?
The main AI gateway benefits are central policy enforcement, cleaner model management, spend visibility by team, easier multi-model operations, and reliable failover. The less visible benefit is consistency, since every team inherits the same access rules, controls, and telemetry.
What challenges do enterprises face when measuring the value of an AI gateway?
Attribution is the hardest part, because gateway gains blur with gains from the AI application, the retrieval layer, or a workflow redesign. Partial adoption also skews results, since teams that keep direct integrations hide both savings and gaps.
How does an AI gateway improve operational efficiency in an enterprise?
A gateway removes repeated work by handling routing, credentials, logging, and policy once for every application. New AI projects reach production faster because teams stop rebuilding the same model controls for each one.
A gateway gives you control over model traffic, and your pilot scorecard shows whether that control pays for itself in spend, risk, and delivery time. The answers your employees get still depend on the context and permissions behind each request, which is the layer we build at Glean. Request a demo to explore how Glean and AI can transform your workplace alongside the governance you already run.