
Why do most AI agent pilots succeed but fail to scale and how do you fix the ROI gap
Most AI agent pilots succeed because they run in controlled conditions, and they fail to scale because context, ownership, governance, workflow fit, and cost discipline were never built into the design. The ROI gap closes when teams build production conditions early and scale only the work users can trust.
The pilot-to-production and ROI gap is the distance between a promising demo and a system teams rely on daily. A pilot proves an idea can work, not that it can operate reliably across real users, systems, and policies. The stakes are rising as agents spread: Gartner predicts 40% of enterprise apps will feature task-specific AI agents by 2026, up from less than 5% in 2025.
The gap matters because enterprise leaders approve budgets on operating results, not demo quality. About 95% of enterprise genAI pilots delivered no measurable P&L return, according to MIT's Project NANDA, while McKinsey found 62% of organizations experimenting with AI agents but only 23% scaling them in at least one function.
How to close the AI agent pilot-to-production gap and fix the ROI gap
To close the AI agent pilot-to-production gap, treat scaling as an operating problem, not a model problem. The real question is rarely whether an agent can generate a useful answer. It is whether the agent returns the right answer, takes the right action, respects permissions, and holds up under real load.
Keep one evaluation standard throughout: if the people who own the work cannot trust the pilot, it is not production-ready. Most failures trace back to fragmented knowledge, weak operational design, unclear accountability, and missing trust controls, not model quality. In one study of multi-agent AI systems, about 44% of failures traced to system design rather than the limits of individual models.
The strongest AI implementation strategies do not begin with a broad rollout. They begin with one high-friction workflow, a clear owner, baseline metrics, and a controlled path to expansion. Position ROI as operational proof: a scaled agent should reduce time, cost, or risk in a workflow people already use.
1. Separate pilot success from production readiness
Pilots succeed because they run on cleaner data, narrower task scope, smaller user groups, and heavier expert supervision than production ever gets. That setup creates false confidence. A pilot can look accurate because a human quietly fixes edge cases, clarifies vague prompts, and catches risky outputs before they spread.
Use a production test instead of a completion rate. Ask what happens when the agent meets messy data, partial context, conflicting documents, changing permissions, and thousands of requests. The math is unforgiving: a 5% error rate that passes under expert review becomes 500 mistakes a day once the agent handles 10,000 requests. Even top models complete only about 30% of multi-step tasks in controlled benchmarks, so demo accuracy rarely survives production conditions.
Judge the agent on trust and repeatability, not demo polish. Score readiness against these signals:
- Data quality variance across real inputs
- Exception rates when context is missing
- Integration depth with live systems
- Approval requirements for risky actions
- Security boundaries and permission scope
- User dependency on human review
Bounded workflows with grounded retrieval and clear tool access are easier to monitor than open-ended agents with weak controls. Reliability also drops as tasks get more complex: in enterprise CRM benchmarks, multi-turn success falls to roughly 35%.
2. Choose one business outcome and one accountable owner
Pick one operational problem the agent must improve, then name one owner with real authority. Strong starting points include repetitive research, case triage, internal support questions, onboarding help, or document-driven coordination. A useful pilot has a baseline, a target state, and a business metric the owning team already cares about.
Shared interest helps, but shared accountability is where projects stall. Organizational alignment in AI matters because agents sit across business operations, IT, security, and knowledge systems. Without a single decision-maker, every production issue becomes a meeting instead of a fix.
That owner is responsible for success criteria, data access, exception policy, change management, and post-launch review. Consider a support team that names first-response time as the metric, assigns the VP of Support as owner, and sets an exception policy for sensitive tickets. If nobody can say which metric should move, who owns the result, and what happens after a miss, the initiative is still a demo.
3. Ground the agent in enterprise context and real workflows
Agents need more than a model. They need access to company knowledge, people context, workflow history, and the systems where work actually happens. An agent that cannot tell a draft policy from the current approved one, or what one user can see from what another cannot, will not earn trust.
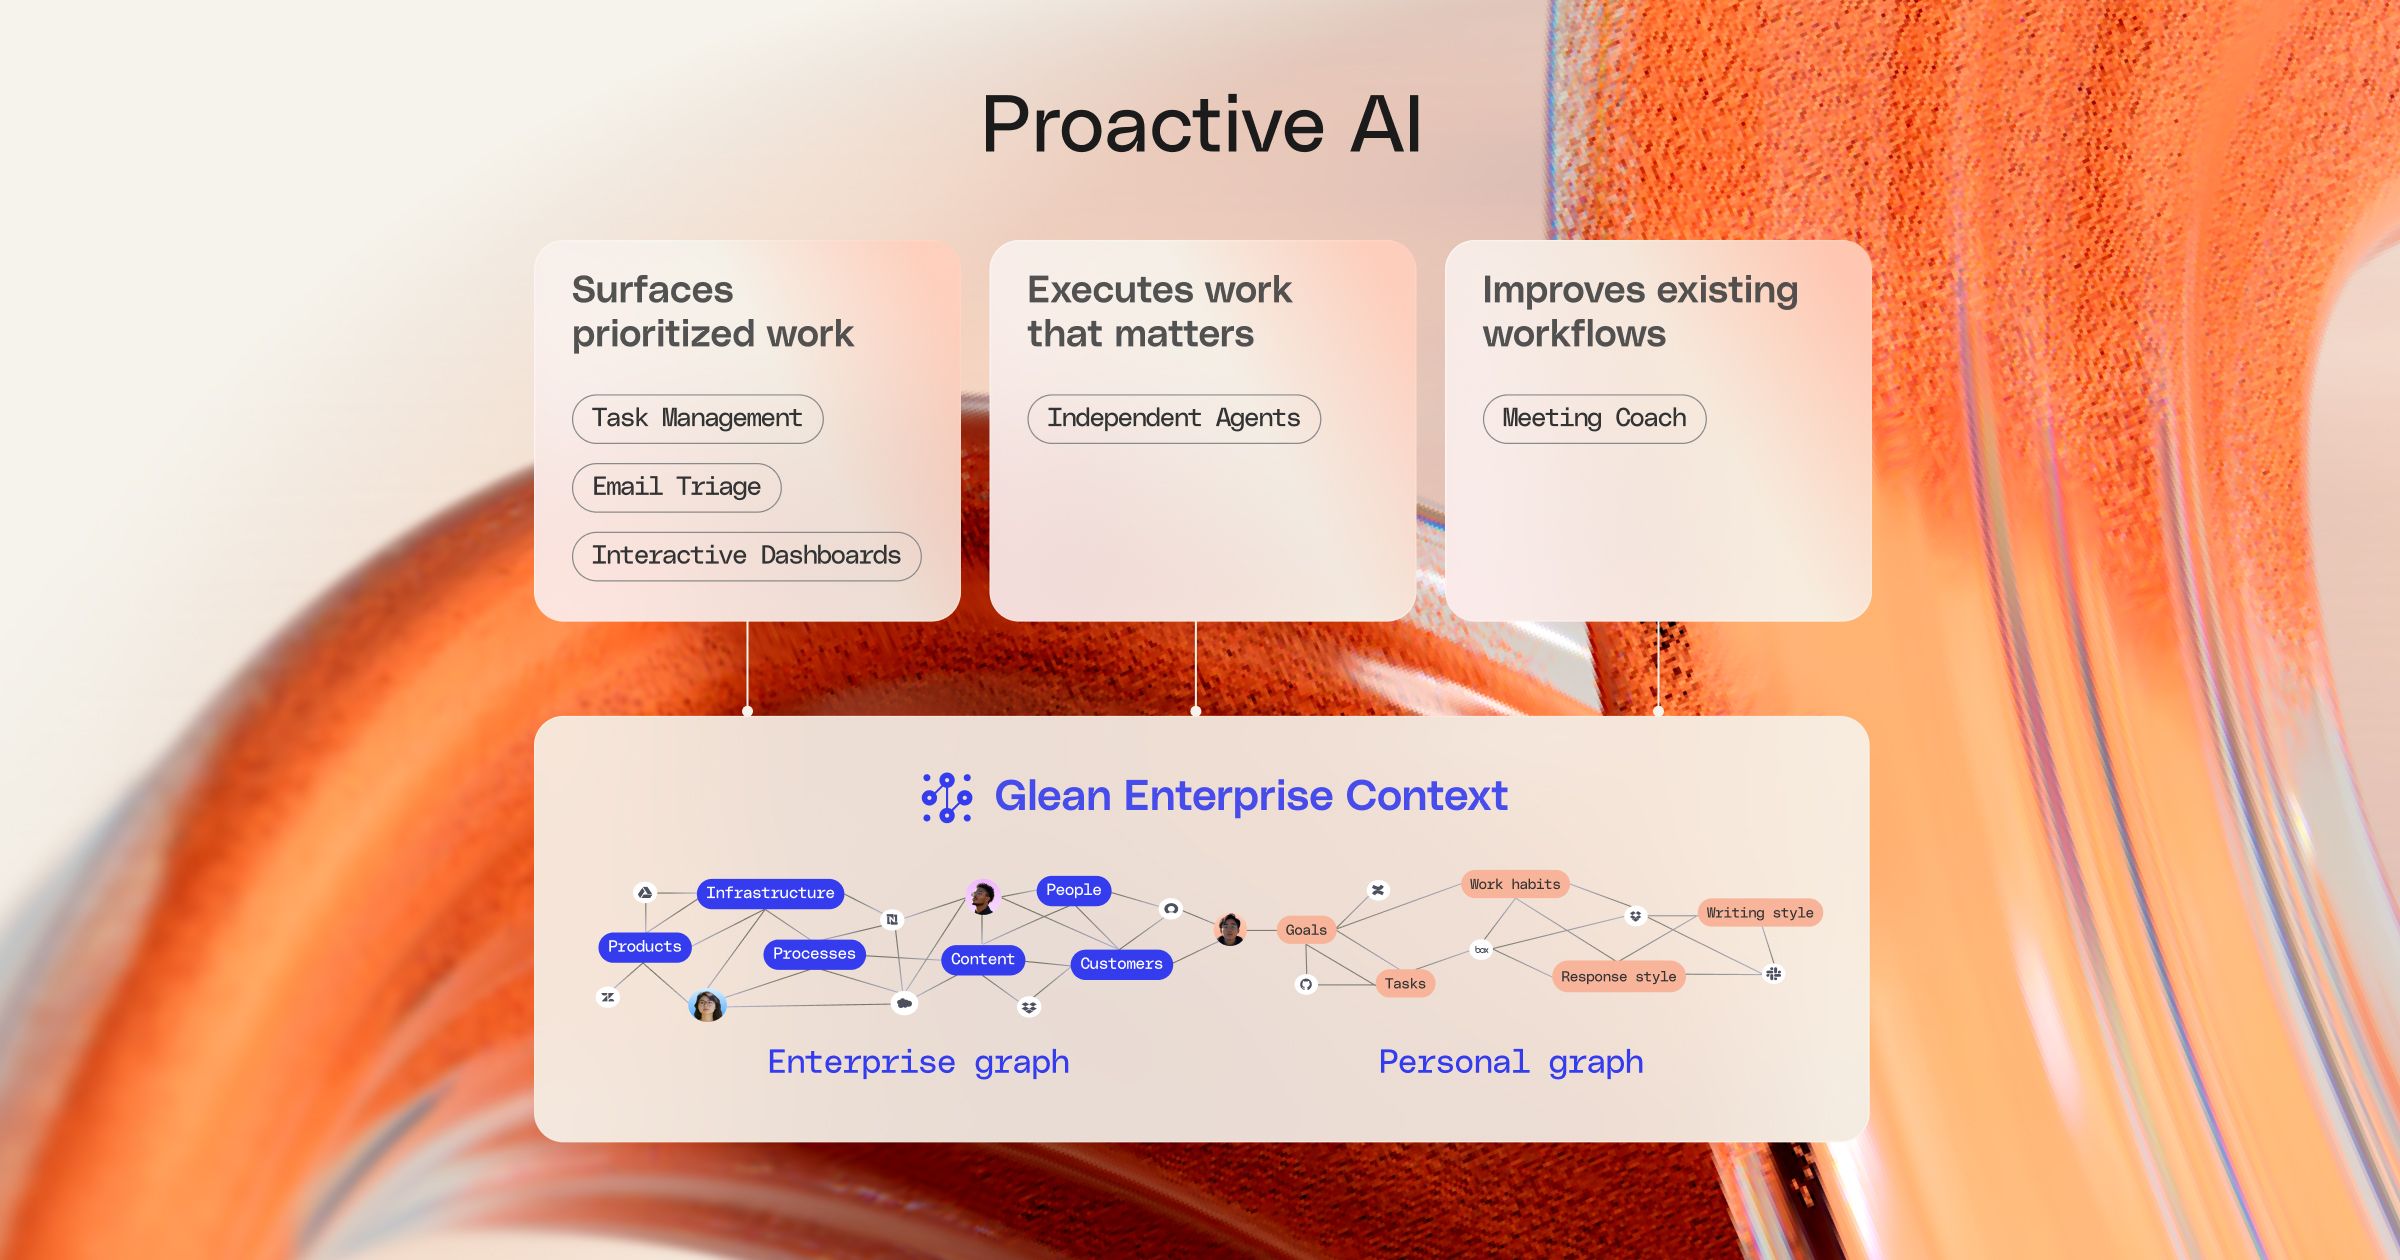
Ground the agent in live enterprise sources rather than copied documents or temporary pilot datasets. Useful context includes documents, tickets, chats, CRM notes, wiki pages, project history, organizational relationships, and existing permissions. Glean grounds answers in company knowledge with permission-aware retrieval, so an agent returns only what each person is allowed to see, with cited sources when the task needs confidence. That depends on connecting to the systems where work happens across more than 275 enterprise sources, not on mocked integrations bolted on later.
MIT's Project NANDA found the roughly 5% of pilots that captured value were workflow-embedded rather than static and generic. The practical rule follows: if an agent cannot fit naturally into the workflow where users already ask, read, decide, and act, adoption flattens before ROI appears.
4. Build governance, permissions, and human review from day one
Build governance, permissions, and human review into the pilot architecture, not after the first incident. Enterprise AI challenges become visible at scale when nobody can explain what the agent used, what it changed, or why it responded the way it did. The agent should respect existing permissions, keep access scoped to what each user can see, and preserve an audit trail for key decisions and actions.
Data governance concerns already slow deployments. AvePoint's State of AI 2026 report found that about 87% of organizations delayed AI deployments by roughly six months, driven by data security and governance concerns rather than model quality. Match the controls to the risk. Gartner warns that applying uniform governance across all agents regardless of autonomy leads to failure, so governance should stay proportional to each agent's autonomy.
Human review is a scaling tool, not a lack of ambition. Automate high-confidence routine work, and route sensitive, ambiguous, or high-impact work to a person. Governance by design also means observability: teams should be able to inspect prompts, retrieved sources, tool calls, actions taken, and exception patterns.
5. Design for reliability, observability, and cost before rollout
Design for reliability, observability, and cost before rollout, because the ROI gap widens most in production. Token spend, orchestration complexity, exception handling, and support overhead climb fast when an agent moves from a curated environment to daily use. DigitalOcean's February 2026 Currents report found that 49% of organizations cite inference cost as the top blocker to scaling agents, and only 10% run fully autonomous agents in production.
Design failure paths as carefully as success paths. Production agents need retries, fallback behavior, clear escalation rules, and graceful handling when context is missing or tools fail. Roll out in stages instead of a full launch: start in audit mode, move to assist mode, then automate only the cases proven low-risk and high-confidence.
Track the operating metrics that reveal true readiness: latency, answer quality, action success rate, exception rate, human override rate, cost per resolved task, and source coverage. An agentic engine that plans and orchestrates multi-step work with grounded retrieval stays easier to monitor and improve. If teams do not know what a successful transaction costs or how often it needs rescue, they are not ready to claim production ROI.
6. Manage the workflow change, not just the technology
People adopt agents that remove friction from work they already do, so the workflow change needs as much attention as the technology. A strong demo does not drive adoption. Redesign the human workflow around the agent: define who asks it for help, when they trust its answer, when they verify it, and what happens when it is wrong.
Treat training as an ongoing practice, not a launch-day event. Teams need clear usage guidance, examples of good requests, escalation paths, and feedback loops that improve the system over time. Place the agent where work already happens, such as Slack, Microsoft Teams, or the browser, instead of asking employees to visit another standalone destination.
Track change signals that show behavior shifting: active usage by the target team, repeat usage, fewer manual handoffs, lower search time, faster resolution, and user-reported trust. Local champions matter here. Managers and subject matter experts normalize the new workflow, surface edge cases, and translate adoption data into operational changes. When people do not change behavior, the pilot has not scaled, even if the technology is live.
7. Measure ROI in operating metrics, then expand in stages
Measure AI project ROI in operating metrics, then expand in stages. The goal is not to prove an agent is impressive. It is to show that a specific workflow now runs faster, more accurately, or with less manual effort than before. Set a baseline before launch and a matched measurement plan after launch, using metrics such as time to answer, time to resolution, ticket deflection, onboarding speed, research hours saved, and cost to serve.
Separate activity from value. Prompt volume, session count, and total messages can signal adoption, but they do not prove business impact on their own. A disciplined approach to measuring ROI on genAI investments ties usage to time saved, business outcomes, and trusted adoption rather than vanity metrics. Compare results by workflow, team, and confidence band, since the clearest gains appear in repeatable tasks with strong context and well-defined actions.
Scale on evidence. MIT's Project NANDA found the winning deployments targeted back-office friction and measured P&L, while much of the spend that produced little return went to high-visibility use cases. Expand to adjacent use cases only after the first workflow shows stable quality, reliable adoption, and measurable impact. The ROI gap closes when teams build production conditions early and scale only what users can trust.
Frequently asked questions
What are the most common reasons AI pilots fail to scale?
The most common reasons are narrow pilot design, unclear ownership, weak workflow fit, missing governance, poor integration with real systems, and no plan for adoption after launch. In practice, pilots fail when they prove technical possibility but never prove operational trust with the people who own the work every day.
How can organizations improve the ROI of AI agent pilots?
Improve ROI by choosing one workflow with clear baseline metrics, grounding the agent in company knowledge and permissions, and measuring business outcomes such as time saved, deflection, or cycle-time reduction. The fastest way to lose ROI is to expand to new use cases before the first one is stable and trusted.
What organizational changes are necessary for successful AI implementation?
Successful scaling usually requires one accountable owner, a cross-functional operating group across business, IT, security, and operations, and a defined review process for changes, exceptions, and access. Organizational alignment in AI matters because agents cut across systems and teams by default, so decisions need a single owner with authority.
What role does data governance play in AI pilot success?
Data governance turns an agent from a helpful demo into a trusted system. It makes the agent use the right sources, respect existing permissions, preserve auditability, and limit risky actions. Gartner recommends governance proportional to each agent's autonomy. Without that layer, scale increases risk faster than it increases value.
How can change management impact the scaling of AI projects?
Change management determines whether people actually use the new workflow. Training, feedback loops, manager support, and clear guidance on when to trust or review the agent all shape adoption. If behavior does not change, the project may be live in production, but it is not delivering enterprise value.
Closing the ROI gap starts with grounding agents in your company's knowledge and building trust controls in from day one. We connect your enterprise knowledge, context, and workflows so your teams get permission-aware, cited answers and can automate the work they trust. Request a demo to see how we can put your AI investment to work.