
Does Your AI Actually Understand How Your Company Works?
AI adoption at work has surged. According to McKinsey's 2025 global survey, 88% of organizations now regularly use AI in at least one business function, up from 78% a year earlier.
Still, most of those tools don't understand how your company works. They're trained on public internet text and recognize general language patterns, not the specific way your organization operates.
Understanding your company means an AI connects your people, content, terminology, projects, and workflows into a coherent picture. That's different from generating text that only sounds plausible.
A general chatbot can define a quarterly business review. A contextual AI knows who runs yours, which template your team uses, and where last quarter's deck lives.
Why General-Purpose AI Falls Short in Business Workflows
General-purpose AI falls short in business workflows because it predicts statistically likely text, not facts grounded in how your company actually operates. Large language models are pattern-matching engines trained on public text. They have no awareness of your org structure, your internal acronyms, your product names, your project histories, or which policies are current versus deprecated.
So when an employee asks "What's our refund policy?" or "Who owns the vendor relationship with our logistics partner?", a general model guesses or returns nothing useful. That gap is where hallucinations turn costly. The model sounds confident about things it has no basis to know. In one documented case, Air Canada was ordered to honor a refund policy that its customer-service chatbot invented.
Point-solution AI tools that connect to one or two apps don't close the gap either. Company knowledge lives across dozens of systems, from document repositories and wikis to messaging, CRMs, and ticketing. Partial context produces partial answers.
How AI Actually Learns Your Company's Data and Context
Contextual AI learns your company by connecting to the systems where work happens and reading that content continuously. Its understanding stays current as people join, projects start, and policies get updated.
Those systems include document repositories, messaging, project tools, CRMs, ticketing, and wikis. Broad native connectivity is what makes this work. Platforms with more than 250 native connectors can index the full stack instead of one or two apps.
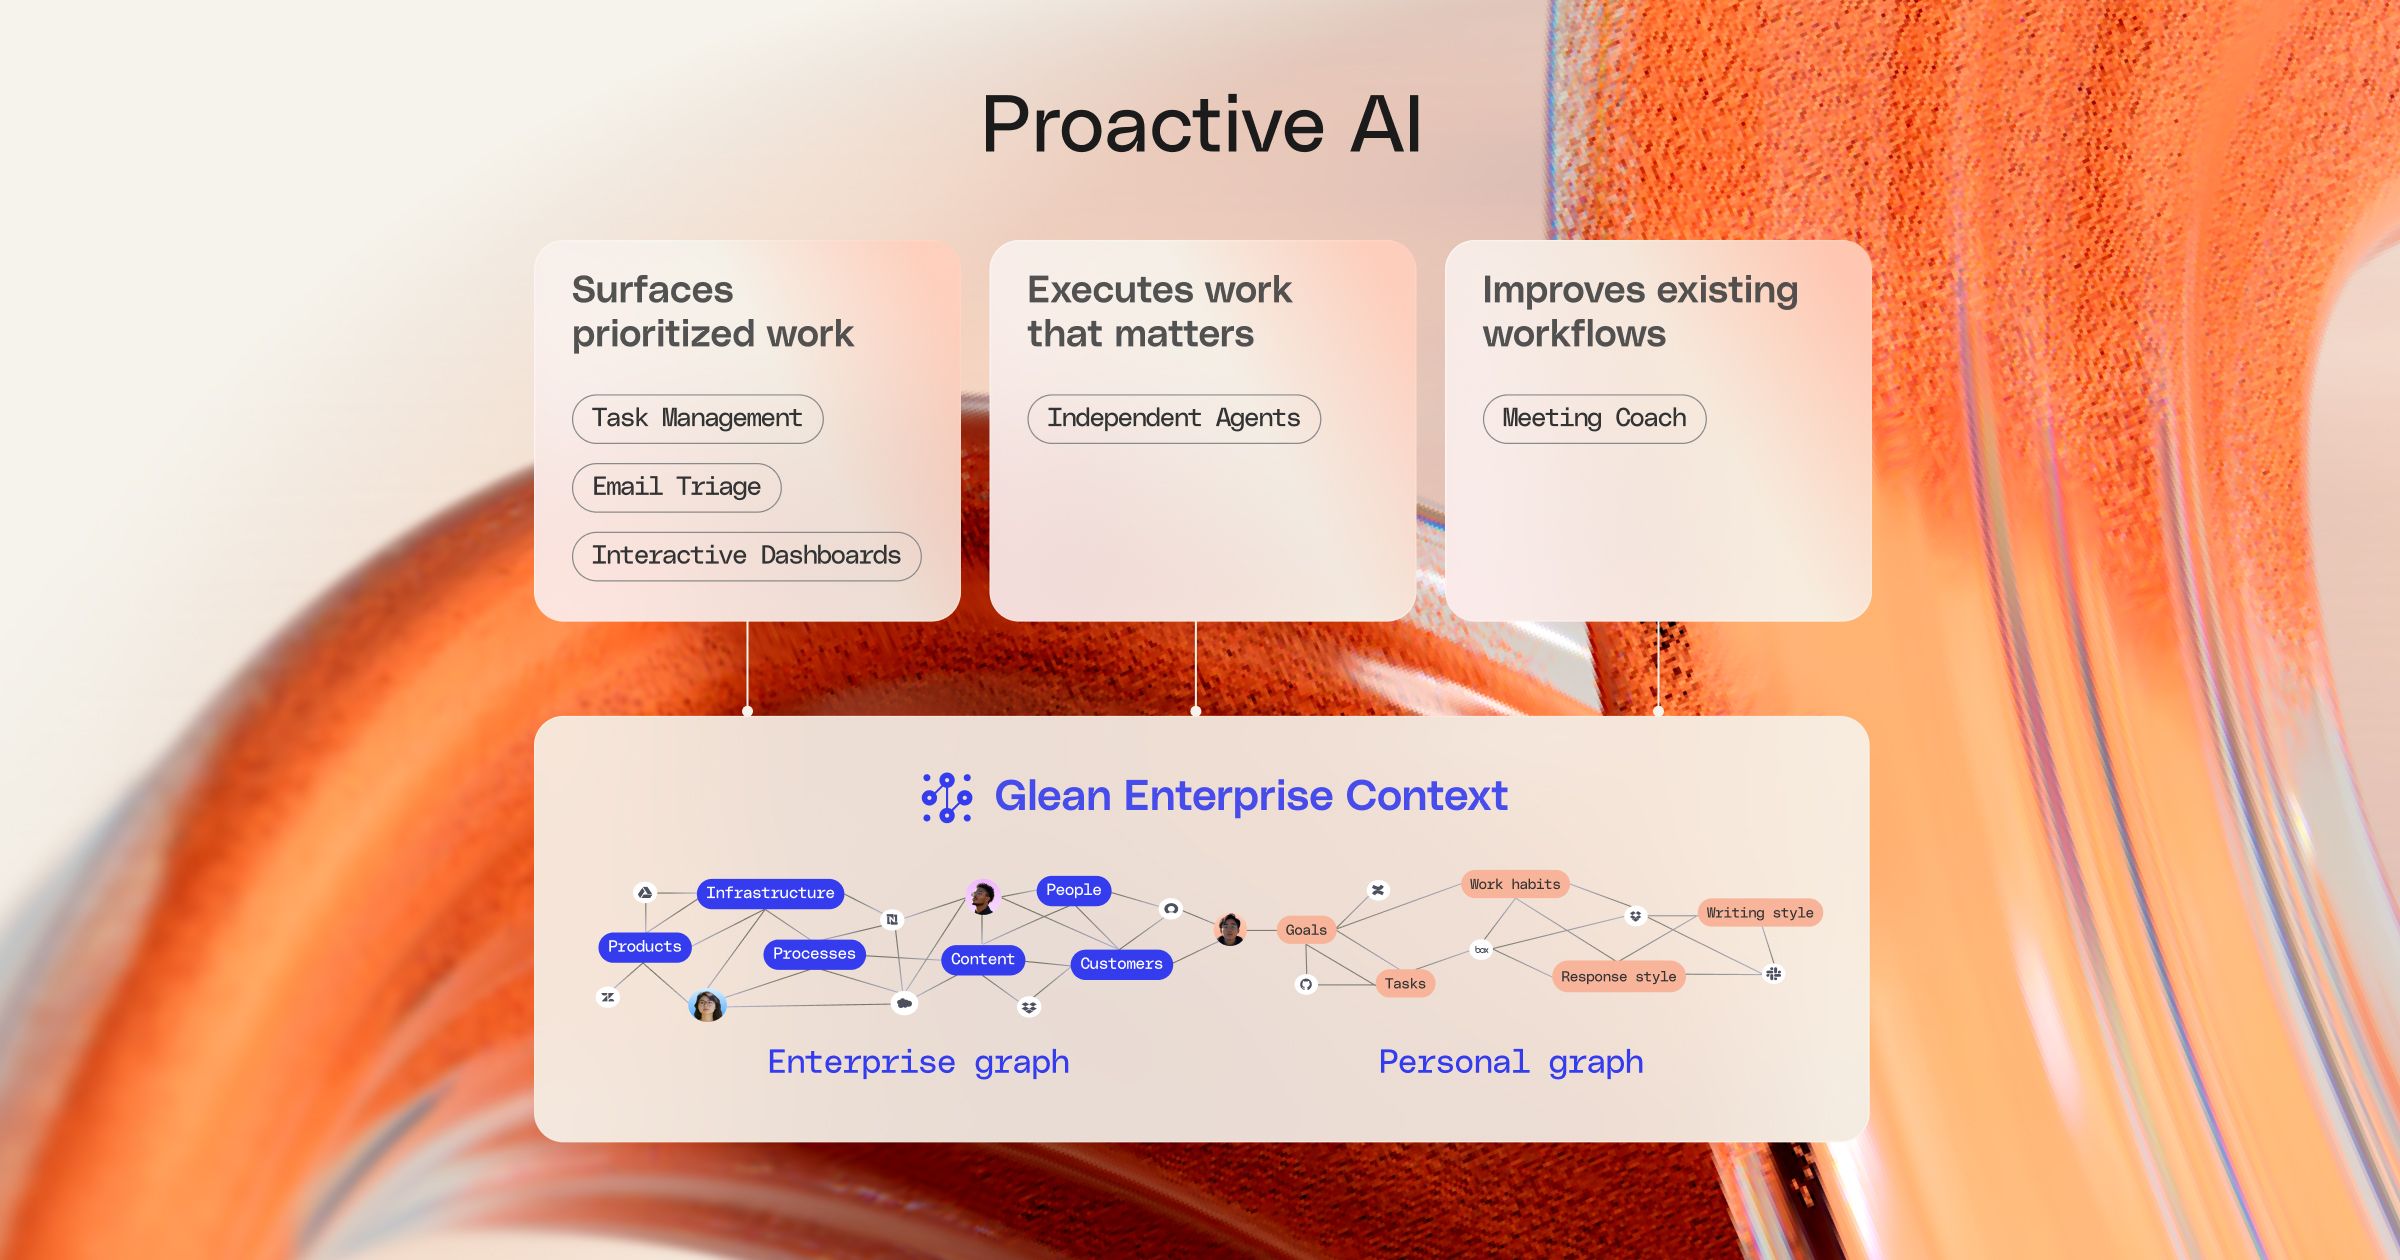
The result is two layers of context. An organization-wide knowledge graph maps relationships between people, content, teams, and topics. A personal graph reflects each person's role, interactions, and relevance signals, so the same query returns different results for a recruiter and a backend engineer.
A knowledge graph is what separates this from keyword search or generic retrieval. It understands that a specific engineering spec relates to a particular product launch, owned by a specific team, and discussed in a particular channel. That web of relationships is how answers get grounded in how your company operates.
What Permissions and Security Have to Do With Real Understanding
Real understanding depends on permissions, because an AI that surfaces the wrong document doesn't understand your company — it exposes it. Any AI reaching internal data has to enforce your existing access controls on every query.
In practice, a salesperson sees only what they're authorized to open, and nothing from restricted HR, legal, or finance files. Permission enforcement has to live in the retrieval layer, upstream of the language model that writes the answer. Bolted on afterward, it leaks.
Enterprise governance adds more. Audit trails record what was asked and retrieved. Data residency controls keep information inside set regions. Contractual zero-day data retention with model providers keeps your proprietary data out of any public model's training.
| Security capability | What it does | Why it matters |
|---|---|---|
| Permission-aware retrieval | Enforces existing access controls on every query | Users only see what they're authorized to see |
| Audit logging | Tracks every search, query, and agent action | Supports compliance and internal security reviews |
| Zero-day data retention | No customer data retained by LLM providers | Proprietary information stays proprietary |
| Data residency controls | Data stays within specified geographic regions | Meets regulatory and sovereignty requirements |
How Contextual AI Improves Workflows Across Teams
Contextual AI improves workflows by grounding answers and actions in each team's own knowledge, so people spend less time reconstructing context — in OpenAI's 2025 enterprise survey, users reported saving 40–60 minutes a day. The payoff looks different by function.
- Support teams resolve issues faster when answers draw on internal knowledge bases and past tickets, not generic scripts.
- Sales teams pull competitive intelligence, deal history, and customer context from CRM data, call transcripts, and internal wikis in one step.
- Engineering teams get natural-language answers about codebases, architecture decisions, and deployment procedures straight from internal docs.
- HR and People teams answer policy questions during onboarding, benefits enrollment, and org changes, grounded in the current version of each policy.
Beyond answers, AI agents automate multi-step work: triaging support tickets, drafting customer responses, compiling weekly reports, and routing requests to the right owner. Each step runs with the same organizational context and access controls as search.
How to Evaluate Whether an AI Solution Truly Understands Your Organization
Test an AI's understanding with questions only an insider could answer, then check the guardrails behind them. A demo that sounds fluent on general topics tells you little about how it handles your data.
Work through a short checklist:
- Ask how many data sources it connects to natively. Broad native connectivity beats custom engineering for every source.
- Run insider-only questions like "Who approved the budget for Project Atlas?" or "What's the current SLA for Tier 2 support tickets?"
- Query from accounts with different access levels to confirm permission enforcement holds.
- Update a policy doc today and measure how soon the new version shows up in answers.
- Look for a knowledge graph, not just document indexing.
- Confirm SOC 2 and ISO 27001 certifications, data residency options, and admin controls.
Answering yes across that list points to a genuine Work AI platform rather than a point solution. Glean, for example, was built around a knowledge graph and permission-aware retrieval from the start rather than adding them later.
Frequently Asked Questions
How can AI be customized to understand my company's specific processes?
It customizes itself by connecting to your tools and learning from your content, activity, and permissions rather than being manually programmed. A company-specific model picks up your dialect, project names, and team structures over time, and it keeps refining as it observes how your teams actually work.
What data does AI need to effectively learn about my organization?
It needs access to the systems where knowledge lives: document repositories, messaging, project tools, CRMs, ticketing, and wikis. It also needs identity and permission data to respect access controls, plus activity signals that show which content is current, who owns it, and how teams use it.
What are the limitations of AI in understanding complex business workflows?
AI can't answer from knowledge that was never written down. It struggles with ambiguous requests and judgment calls that depend on unstated context. It only knows what it can access, so gaps in connected sources become gaps in answers. Human review still matters for high-stakes decisions.
How long does it typically take for AI to start delivering value after deployment?
In our experience with customers, value usually starts with search. Once Glean Search connects your tools and returns cited answers, teams find what they need in their first weeks. Answer quality improves as the Enterprise Graph learns your organization, and automation value follows as teams add Glean Agents.
Does AI retain or use my company's data to train public models?
It shouldn't. With contractual zero-day data retention, model providers keep none of your data, so your proprietary information never trains a public model. Look for that commitment in writing, along with audit logging and data residency controls, before you connect sensitive systems.
Real understanding of how your company works depends on context, not just a capable model. We connect your knowledge, permissions, and workflows so you get cited answers grounded in what you can see, plus automation that runs where you already work. Request a demo to see how we put your company's real context behind every answer and every workflow.